Build & Train a GLM-5.3-Flash Model From Scratch with Python
This tutorial builds and trains a 25.7M parameter language model inspired by GLM-5.3-Flash from random initialization, using synthetic coding data on an RTX 3080 Ti (the code also supports CPU, Apple Silicon MPS, and CUDA). It covers designing a 260-token byte-level tokenizer, implementing the transformer architecture (hyperconnection residual streams, a linear/sparse attention hybrid, mixture of experts, and weight tying), adding a small vision module for digit recognition, and running reinforcement learning (RLOO) experiments comparing reward types, temperature, and group size. By the end, the model goes from failing all held-out coding tasks to solving 16 of 24 after RL, with pass@8 improving from 25/64 to 34/64, though the creator is explicit this measures only a narrow synthetic benchmark, not general coding ability. The code is hosted in a GitHub repository; no specific programming framework or install steps are stated in the source.
Goal: [00:00] Build and train a 25 million parameter GLM 5.3 Flash model from scratch on a standard CPU.
- Model name: [00:20] The model is called GLM 5.3 Flash, also referred to as Ox Alpha, described as the latest viral model from Drupal AI.
- Actual model specs: [00:55] The trained model is 25.7M parameters, trained on synthetic coding data only, on an RTX 3080 Ti, verified with exact unit tests.
- Benchmark result: [00:59] Sampled pass@8 across all eight task families improved from 25/64 to 34/64, a +53.1 percentage point gain.
- Caveat: [00:59] This result describes only the synthetic benchmark and does not establish broad coding ability.
+ 81 more takeaways
- Context: [01:02] The course references a real Anthropic job posting for a Research Engineer, Domain Scaling role, focused on designing data, environments, and reward signals rather than inventing new model algorithms.
- Claim: [01:04] The presenter claims this Anthropic job posting describes 95% of AI researcher roles today.
- Context: [01:21] Claude Code and Codex are cited as AI that can code experiments autonomously, with the human researcher's job reduced to having high-level ideas about which experiments to run.
- Code shown: [02:23] A forward pass code snippet is shown (embedding, streams, layers, final_norm); code continues off screen, not fully shown.
- Scale note: [02:36] The tutorial model has 25 million parameters versus the released model's 320 billion, so it can train on CPU, GPU, or MacBook.
- Research question: [03:19] The RL research question tested reward type (binary or partial), penalty strength, temperature (0.20 or 0.80), and group size (4 or 16) for improvement on unseen coding tasks.
- Resource: [04:29] The presenter invites viewers to join a Skool community called 'Become AI Researcher.'
- Tokenizer background: [05:15] Real LLMs use byte pair encoded (BPE) tokenizers totaling 150,000 to 300,000 tokens.
- Tokenizer design: [05:45] This tutorial model makes each ASCII character its own token, a vocabulary of 260 tokens, with token IDs 0-3 reserved as control tokens so each byte value is stored as token ID plus 4.
- Design rationale: [06:35] With a 250,000-token vocabulary on a small model, about 95% of parameters would go into vocabulary conversion matrices and only 5% into the actual layers.
- Concept: [07:12] Each input token is replaced with a vector embedding encoding that token's meaning.
- Concept: [07:57] These embedding vectors are learned by the LLM during training.
- Concept: [08:31] The transformer turns the processed prompt into a probability distribution over the entire vocabulary to predict the next token.
- Architecture: [08:52] GLM 5.3 Flash uses a linear/sparse attention hybrid, mixture of experts, DeepSeek's manifold-constrained residual connections (hyperconnections), and a shared matrix for input/output vocabulary embedding conversion.
- Spec comparison: [09:28] The released GLM model has 320B parameters, 45 layers, 8 of 288 active experts, a BPE tokenizer with 154,880 tokens, and 1M context.
- Spec comparison: [09:28] The teaching model built here has 25.7M parameters, 12 layers, 2 of 8 active experts, a byte tokenizer with 260 tokens, and 192 context.
- Before/after RL: [09:53] Before reinforcement learning the teaching model fails all tasks, and after RL it succeeds on 16 out of 24 simple tasks like writing a Python function that multiplies input by two.
- Code walkthrough: [10:54] A token ID acts as an address that the embedding layer uses to retrieve that token's learned vector from a weight matrix, which can be 95% of parameters in a small model.
- Code walkthrough: [11:46] The vector x is expanded via unsqueeze(2) then expand(-1,-1,4,-1) into four identical starting residual streams (manifold-constrained hyperconnections from DeepSeek and ByteDance).
- Architecture: [12:19] The model uses multiple residual streams described as highways carrying different types of information forward through the network.
- Architecture: [13:00] The hyperconnection streams get merged into a single hidden dimension vector at the end of processing.
- Architecture: [13:17] That final hidden state is transformed into a probability distribution over the entire vocabulary using a weight matrix.
- Design choice: [13:49] The same weight matrix used for the initial token embedding lookup can also be reused for the final vocabulary projection, saving parameters.
- Architecture: [14:28] RMSNorm normalizes vectors before each sublayer to keep numbers near a scale of 1, -1, or 0 so repeated multiplications don't blow up or vanish.
- Architecture: [15:29] Positional encoding (RoPE) rotates pairs of dimensions in each token vector based on token position, letting the transformer learn order from the rotation.
- Architecture: [16:00] GLM uses NoPE (no explicit position rotation) in its main attention, applying RoPE only in the sparse indexer.
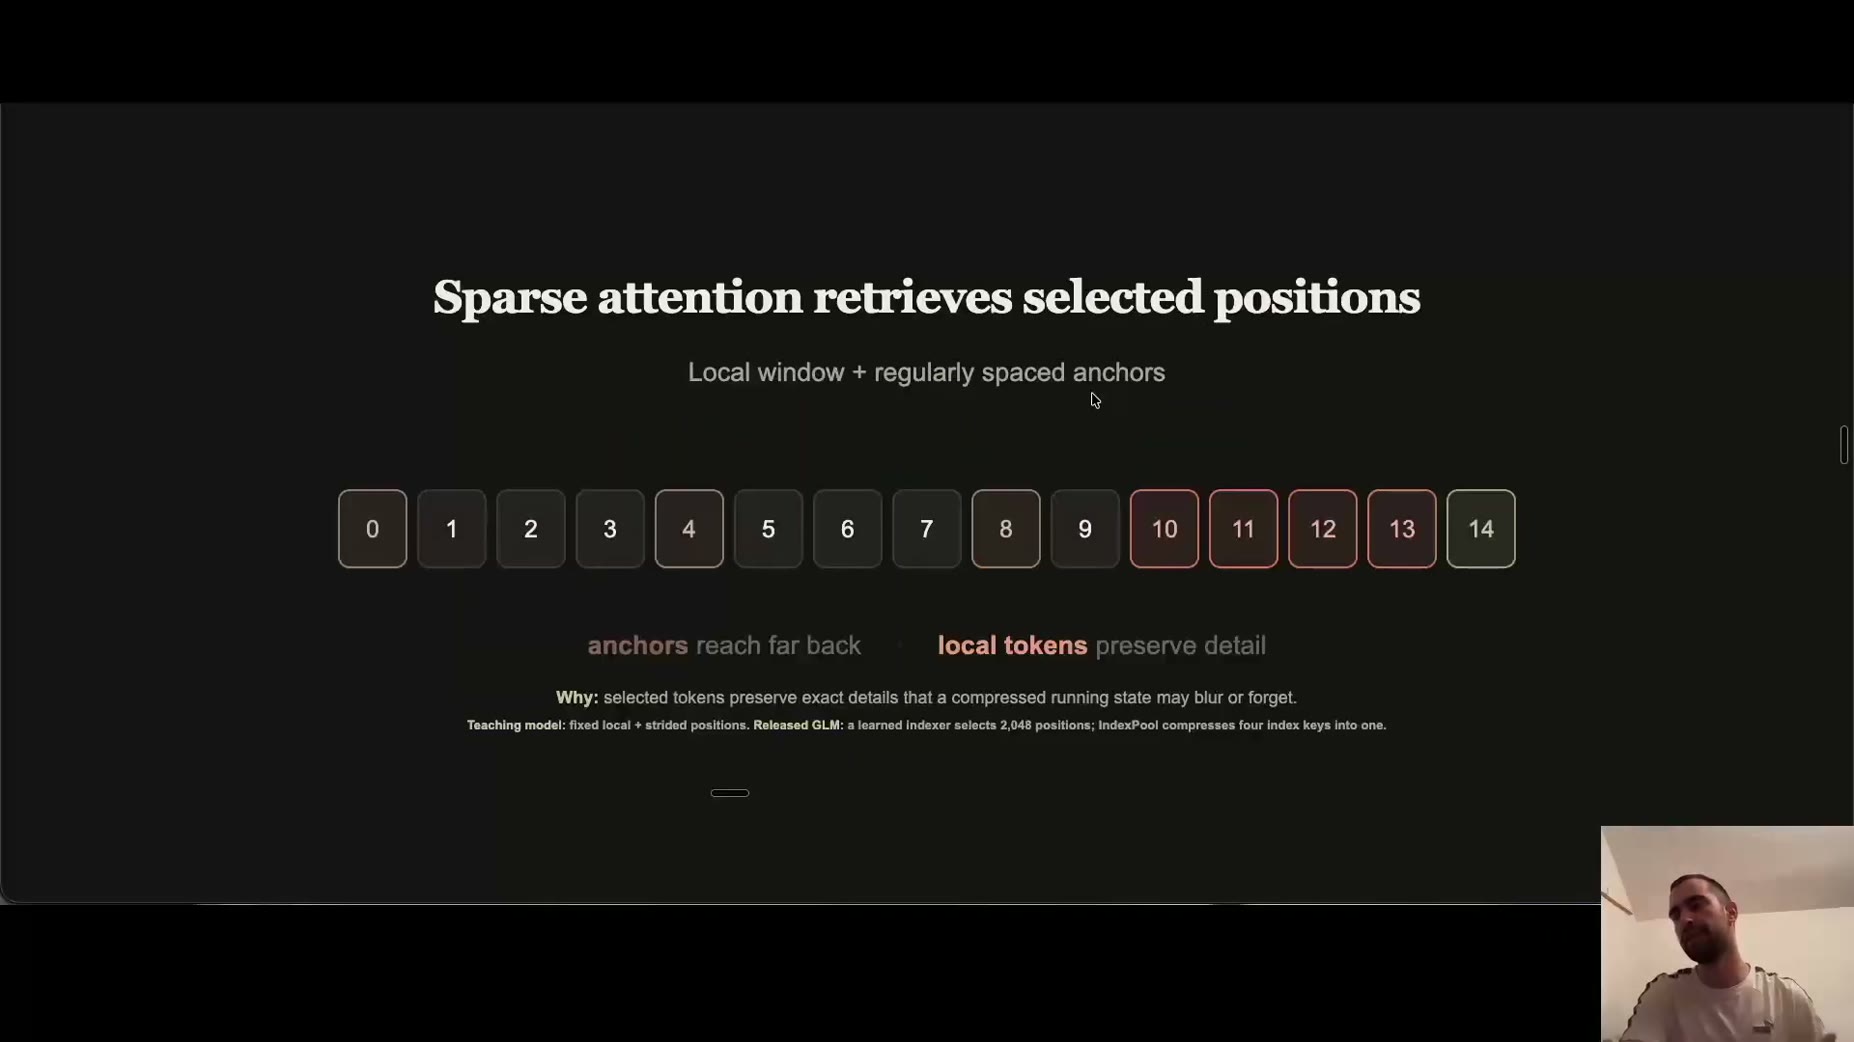
- Architecture: [16:36] The sparse indexer is a lighter, cheaper attention mechanism that finds the most relevant tokens (e.g. 1,000-2,000) for full regular attention to process.
- Design difference: [18:12] Only the sparse indexer contains positional encodings in the released GLM attention mechanism, while the teaching model applies RoPE directly inside both attention types for simplicity.
- Layer rhythm: [18:46] The teaching model's 12 layers follow a repeating four-layer rhythm of three linear layers plus one sparse layer, while the released GLM uses 34 KDA linear layers plus 11 sparse layers across 45 layers.
- Code: [19:53] Every fourth layer is set to sparse attention and all other layers use linear attention, selected by the conditional expression 'SparseAttention if sparse else LinearAttention'.
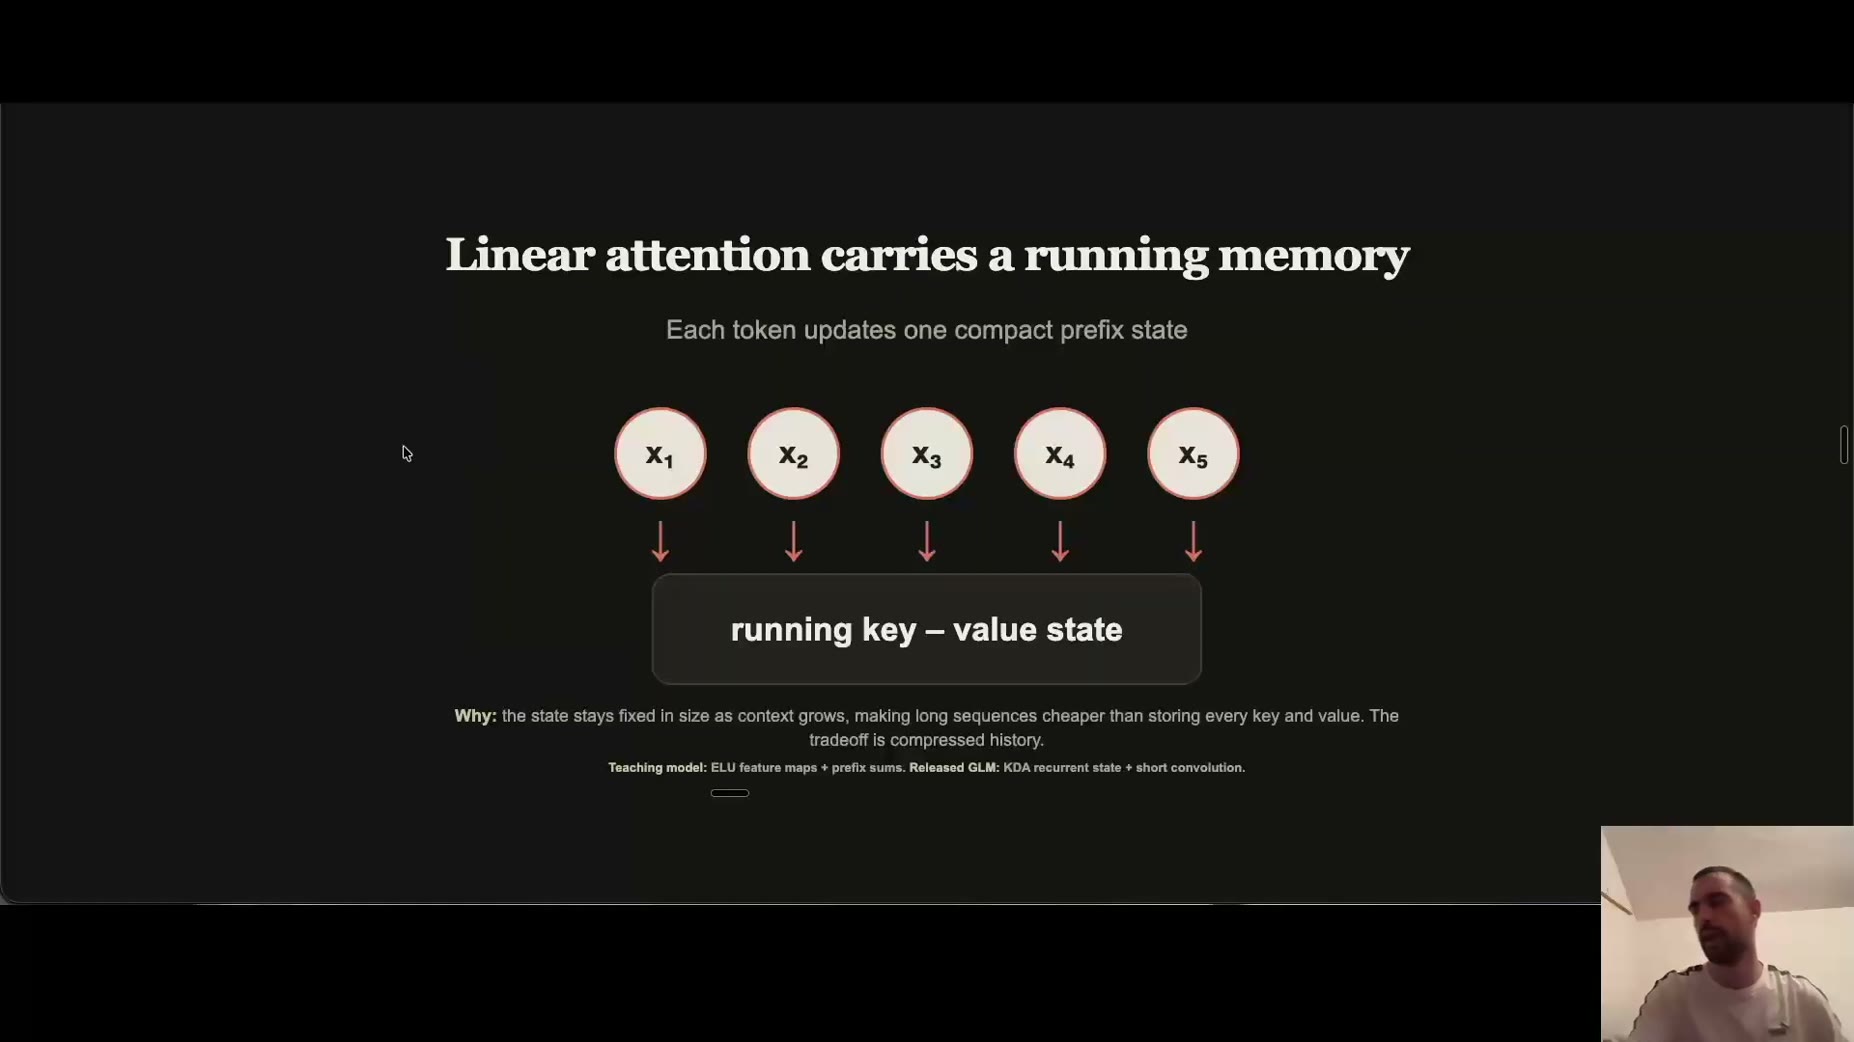
- Architecture: [20:00] Linear attention keeps a running key-value state that stays fixed in size as context grows, making long sequences cheaper at the cost of compressed history.
- Implementation detail: [20:00] The teaching model's linear attention uses ELU feature maps plus prefix sums, while the released GLM uses a KDA recurrent state plus short convolution.
- Implementation detail: [20:28] The teaching model's sparse attention uses fixed local plus strided positions, while the released GLM uses a learned indexer selecting 2,048 positions and an IndexPool that compresses four index keys into one.
- MoE detail: [20:45] The teaching model routes each token to 2 of 8 experts plus 1 shared expert, while the released GLM routes each token to 8 of 288 experts plus 1 shared expert.
- MoE detail: [21:04] Every token passes through the shared expert, which learns common information so the other routed experts don't need to waste capacity on it.
- Architecture difference: [21:42] The released GLM gives each sublayer its own hyperconnection, with attention reading one learned mixture and writing its update back across four preserved streams before MoE reads a new mixture and routes a second update back.
- Architecture difference: [21:44] The miniature model uses one simpler hyperconnection wrapping attention and MoE together, not restoring four streams between them.
- Code: [22:20] The hybrid block's forward pass is: x = x + attention(attention_norm(x)); ffn, usage = moe(ffn_norm(x)); return x + ffn, usage.
- Code: [22:24] The input and output share one matrix via 'self.output.weight = self.embedding.weight', a technique called weight tying.
- Multimodal: [23:06] GLM-5.3-Flash also processes images, and the production model and the miniature use the same high-level path for converting images into patch embeddings and tokens.
- Vision detail: [23:38] A 32x32 RGB image is divided into an 8x8 patch grid, and each 2x2 group of patches becomes one vector, turning the grid into a 4x4 set of 16 image tokens, using two vision blocks in the small coded version.
- Repo description: [24:02] The GitHub repository is described as a readable 25.7M-parameter language model inspired by GLM-5.3-Flash, trained from random initialization and improved with executable-reward reinforcement learning, supporting NVIDIA CUDA, Apple Silicon MPS, and CPU execution.
- Vision training: [25:00] The vision model was trained with 120 optimizer steps at batch size 40 on CPU, taking 4.3 seconds for both models, learning to identify digit images such as predicting the token for digit seven.
- Evaluation detail: [26:05] The evaluation holds out exact pixels (new shifts, colors, intensities, noise) rather than unseen digit categories, testing recognition of new renderings.
- Concept: [26:51] In pre-training the model imitates data by learning what tokens mean, while in reinforcement learning it learns to generate answers it judges correct.
- Training detail: [27:11] A 100-byte sequence creates about 99 next-byte prediction targets, and randomized function names reduce exact string memorization.
- Training detail: [27:28] AdamW was used instead of Muon for simplicity, with router balance keeping experts useful and gradient clipping limiting unstable jumps.
- Training result: [27:57] 173,237 training bytes moved the model from arbitrary byte repetition to a coherent executable completion for the prompt 'Return two times x.'
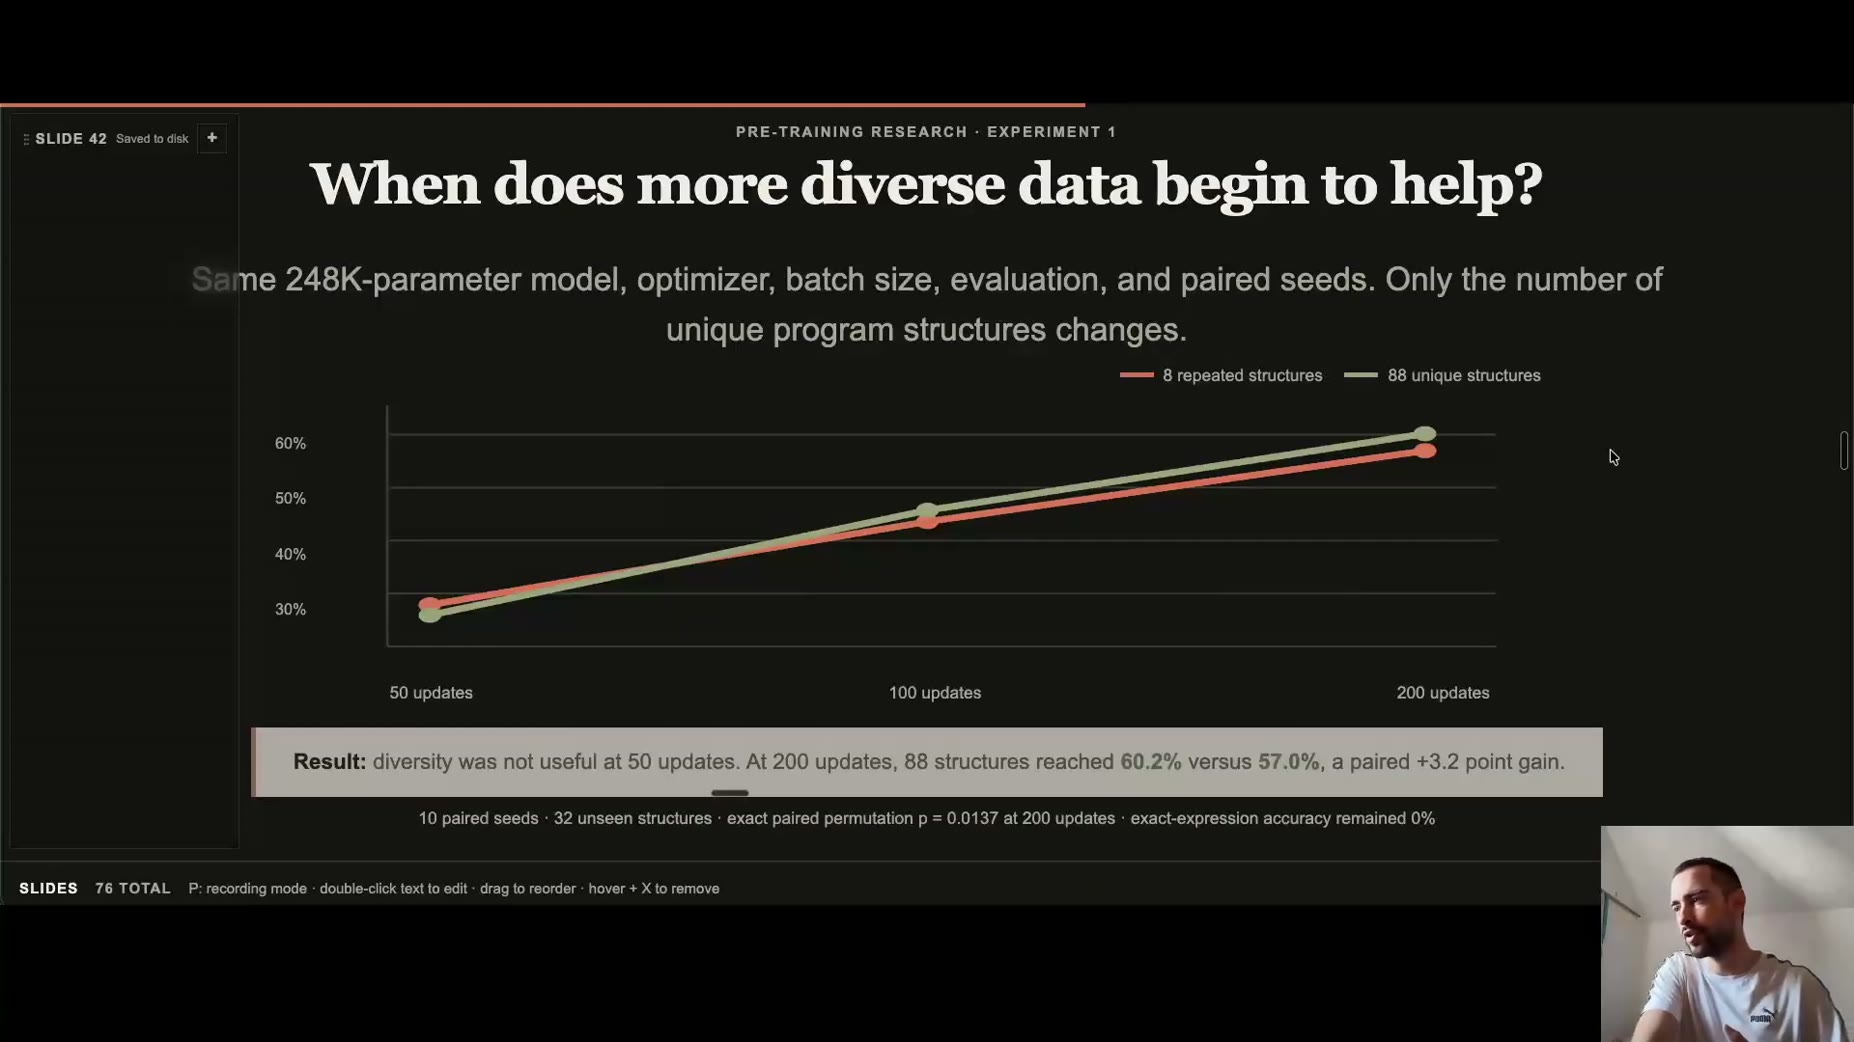
- Experiment result: [28:13] With a 248K-parameter model, data diversity was not useful at 50 updates, but at 200 updates 88 structures reached 60.2% versus 57.0% (a paired +3.2 point gain, p=0.0137 across 10 paired seeds and 32 unseen structures).
- Experiment result: [29:07] All 10 paired seeds favored interleaving over homogeneous blocks, with a bootstrap 95% interval of +7.6 to +11.7 points and exact paired permutation p=0.00195 on held-out target-byte accuracy.
- Experiment design: [29:31] The curriculum hypothesis tested whether repeating simple patterns for 100 updates before expanding to 88 structures for the final 100 updates would beat diverse interleaving from the start.
- Experiment result: [30:21] The curriculum beat repeating only 8 structures by +2.6 points (p=0.0117) but did not beat diverse interleaving from the start (p=0.2148).
- Context: [30:59] Single rollout reinforcement learning task completions can take days at frontier labs like OpenAI and Anthropic.
- Result: [32:04] Post-training on a small example moved the model from 4% correct answers to 45% correct answers.
- Benchmark: [32:46] Before reinforcement learning the model scored 0 out of 24 on new function names from the three trained operation families; after RL it scored 16 out of 24, using strict pass@1.
- Definition: [33:00] Pass@1 means one try judged correct or incorrect, while pass@8 means eight tries counted correct if any one succeeds.
- Statistics: [33:27] The bootstrap 95% interval for the RL gain was +25.0 to +53.1, described as statistically clear but not proof of broad coding improvement since evaluation reused trained operation families and prompt templates.
- Example: [34:23] In the example (return 2 times x), before RL the model returned x times x, and after RL it returned x times 2.
- Concept: [34:36] Reinforcement learning increases the probability that the correct answer will be generated based on all the parameters, rather than copying an answer from a label.
- Reward structure example: [34:47] One reward structure example: plus one if all tests pass, zero for valid format but wrong answer, and minus one for invalid Python syntax.
- Context: [35:57] DeepSeek is no longer putting substantial effort into GRPO because the algorithm is already good enough and further effort yields better returns on data and post-training environments instead.
- Verifier detail: [36:15] A verifier runs hidden tests that are never revealed in the prompt, validating source, compiling it, running it, and checking that outputs match type and value for every test case.
- Risk note: [36:20] Models like GPT, Fable, and Astra are possibly going to try to hack or inspect the verifiers.
- GRPO detail: [36:34] In GRPO, the same question can be given to the model to generate 16 different answers, which are each rewarded based on correctness.
- GRPO detail: [36:59] The method calculates an 'advantage' as the reward of one answer minus the mean of the other rewards, so better-than-average answers become more likely and worse ones become less likely, without a separate critic model or human review.
- Fine-tuning scope: [37:37] Only the last transformer block, the final normalization layer, and the tied output head are updated, totaling 2.19M parameters.
- Rationale: [37:53] Freezing earlier layers avoids forgetting knowledge encoded in those layers while training on the new reinforcement data.
- Note: [38:16] LoRA and full-model updates are alternative techniques besides updating just the last few layers.
- Guidance cited: [38:38] MIT's guidance cited is to start from small toy examples before scaling to complex experiments.
- Algorithm: [38:49] The RLOO algorithm generates a group of 16 completions per task, computes rewards, derives leave-one-out advantages, and updates via policy gradient loss with no reference completion or critic.
- Training tasks: [39:35] Training tasks were Python operations: increment, double, and even.
- Result: [40:35] Results showed improvement from 0/24 to 16/24 on the trained behaviors after executable feedback.
- Ablation result: [41:17] In ablation experiments, group size 4 outperformed group size 16, and temperature 0.2 outperformed higher, more random temperatures.
- Ablation result: [41:32] Reward shaping variants (binary 0/1, partial rewards, no invalid penalty, hard invalid penalty) all performed the same on the speaker's dataset.
- Methodology note: [41:45] With only small dev sets you can rank candidates but cannot establish a reliable winner; 500 to 5,000 examples give better insights.
- Ablation result: [41:55] Across three training seeds (31415, 27182, 16180), group size 4 beat group size 8 on two seeds but lost on one, and the 95% interval of -6.7% to +1.7% crosses zero.
- Methodology note: [42:33] Paper reviewers will ask for three seeds, and all three must agree before a conclusion like 'Group 4 is better than Group 8' can be made.
- Conclusion: [42:46] None of the speaker's experiments produced statistically significant improvements.
- Final result: [43:05] The honest conclusion is that a complete miniature research pipeline was built and narrow learning was measured, not a reproduction of the 320B system or general coding intelligence.
- Final result: [43:16] Pre-training taught the model to write Python and eight operation patterns, vision taught it to recognize images into the language model, and reinforcement learning improved the increment and double operations.
- Closing note: [43:51] Consistency matters more than intensity: posting once a week forever beats posting five days in a row then stopping.
tree = validate_source(source, task.entry_point) exec(compile(tree, "candidate.py", "exec"), namespace) function = namespace[task.entry_point] for arguments, expected in task.cases: actual = function(*arguments) passed += int(type(actual) is type(expected) and actual == expected)
embedded = self.embedding(input_ids) streams = embedded.unsqueeze(2).expand(-1, -1, self.config.streams, -1).contiguous() usages = [] for layer in self.layers: streams, usage = layer(streams) usages.append(usage) hidden = self.final_norm(streams.mean(dim=2)) return self.output(hidden), torch.stack(usages)
def forward(self, x): x = x + self.attention(self.attention_norm(x)) ffn, usage = self.moe(self.ffn_norm(x)) return x + ffn, usage
self.output.weight = self.embedding.weight
How this brief was shaped: Deep-Dive (coding / tutorial / how-to) · confidence Medium
Transcript explicitly frames this as a tutorial to build and train a model from scratch with code on GitHub, walking through embedding and token ID logic, and OCR shows a code editor plus a before/after RL benchmark table with pass@8 percentages and PASS/FAIL unit tests.
The lens sets this brief's structure, never its facts — every claim is held to the same citation and fact-check standard.